
Reinforcement Learning with GRPO, Clearly Explained!!!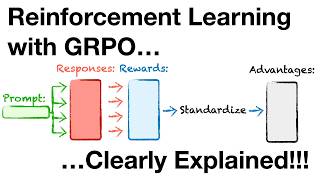
Reinforcement Learning with GRPO, Clearly Explained!!!
How GRPO trains smarter LLMs
StatQuest with Josh Starmer
How GRPO trains smarter LLMs
Agents don't just work, they learn.
Why iterative tuning kills models.
Best Practices
AI teams often treat human behavioral data as a shortcut to intelligence: watch what people do, i...
The brutal reality of AI scaling.

Why open-source AI is safer.
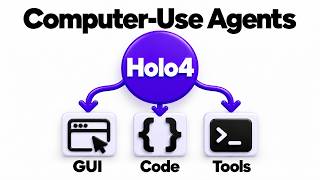
Agents that switch tools on the fly.
AI is shifting: safer, not slower.

Primer
Open Alchemy is IBM Research’s bet that enterprise agents fail less from missing orchestration th...
Best Practices
If you are building agents that plan, act, and call tools, the real danger is not that they are a...
Faster than LLMs, cheaper than AI.
IBM targets the future of AI agents.
AI models can hack their own systems
Expert tips for real AI mastery.
Your work habits are now AI fuel.

Grok 4.6: Powerful, but slower.
Robots finally learn to generalize.
Your AI is lying. How to fix it.


Agents that build their own tools.

Training agents as world simulators.