
Why It Matters
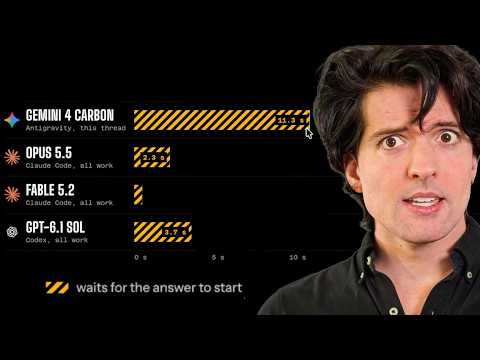
This critique serves as a bellwether for the 'infrastructure layer' of the AI race. As frontier models reach parity in reasoning capability, the competitive advantage is shifting toward reliability, latency, and developer ergonomics. If a powerful model is hidden behind broken caching and 11-second delays, it is effectively invisible to the professional engineering market.
Strategic Implications
Google’s current approach, characterized by a mismatch between model hosting and developer tool requirements, risks ceding the high-value developer market to competitors like Anthropic and OpenAI. The pricing increase scheduled for December 2026, if implemented without fixing these technical barriers, may drive even loyal developers to abandon the ecosystem entirely.
Evidence & Hype Audit
The speaker relies heavily on personal audit data, which introduces a potential bias toward his specific development workflow. However, the specificity of his complaints—particularly the 11-second latency and cache-write failure rates—provides a verifiable checklist for Google’s internal teams to investigate. His personal characterizations of leadership are anecdotal and aggressive, which adds narrative friction but lacks empirical grounding.
Counterarguments
One could argue that the speaker is over-indexing on agentic workflows, which are notoriously sensitive to latency. For less interactive use cases, such as bulk data processing or high-throughput batch generation, Gemini 4 Carbon’s performance might remain competitive or even superior if its reasoning capability outweighs its startup costs.
Who Should Care
- AI Infrastructure Engineers: To understand the critical failure points in high-latency inference environments.
- Product Managers at Big Tech: To gauge the cost of 'developer experience' debt in AI services.
- Professional Developers: To evaluate if the cost and friction of Gemini are justified by its current output quality.
What To Do Next
- Audit existing latency metrics in agentic pipelines.
- Document and report cache-inconsistency patterns to provider support.
- Test alternative models to determine if current bottlenecks are model-specific or platform-specific.
- Re-evaluate cloud-provider spend ahead of December 2026 pricing changes.
- Prioritize modular agent designs that minimize reliance on any single high-latency model.